125 posts · page 2 of 6
Salary Data API: Three Sources, Three Different Numbers
Indeed says the median software engineer earns 136k. Levels.fyi says 298k. Both are right, and the field that explains it is the sample count.
Telegram Channel Data Without a Bot Token
Telegram publishes view counts no other platform gives you. They arrive as 926K and 24.2M, already rounded, and they are lifetime totals not velocity.
Insider Trading API: What Form 4 Data Actually Tells You
A director sold 1,848,501 shares for $410,843,671. The filing arrived two days later, and that lag is the most important field in the response.
PitchBook Pricing and Cost: Is There an API Instead?
PitchBook publishes no price and no public API. Free alternatives return which rounds a company raised and what type, not how much, when or the valuation.
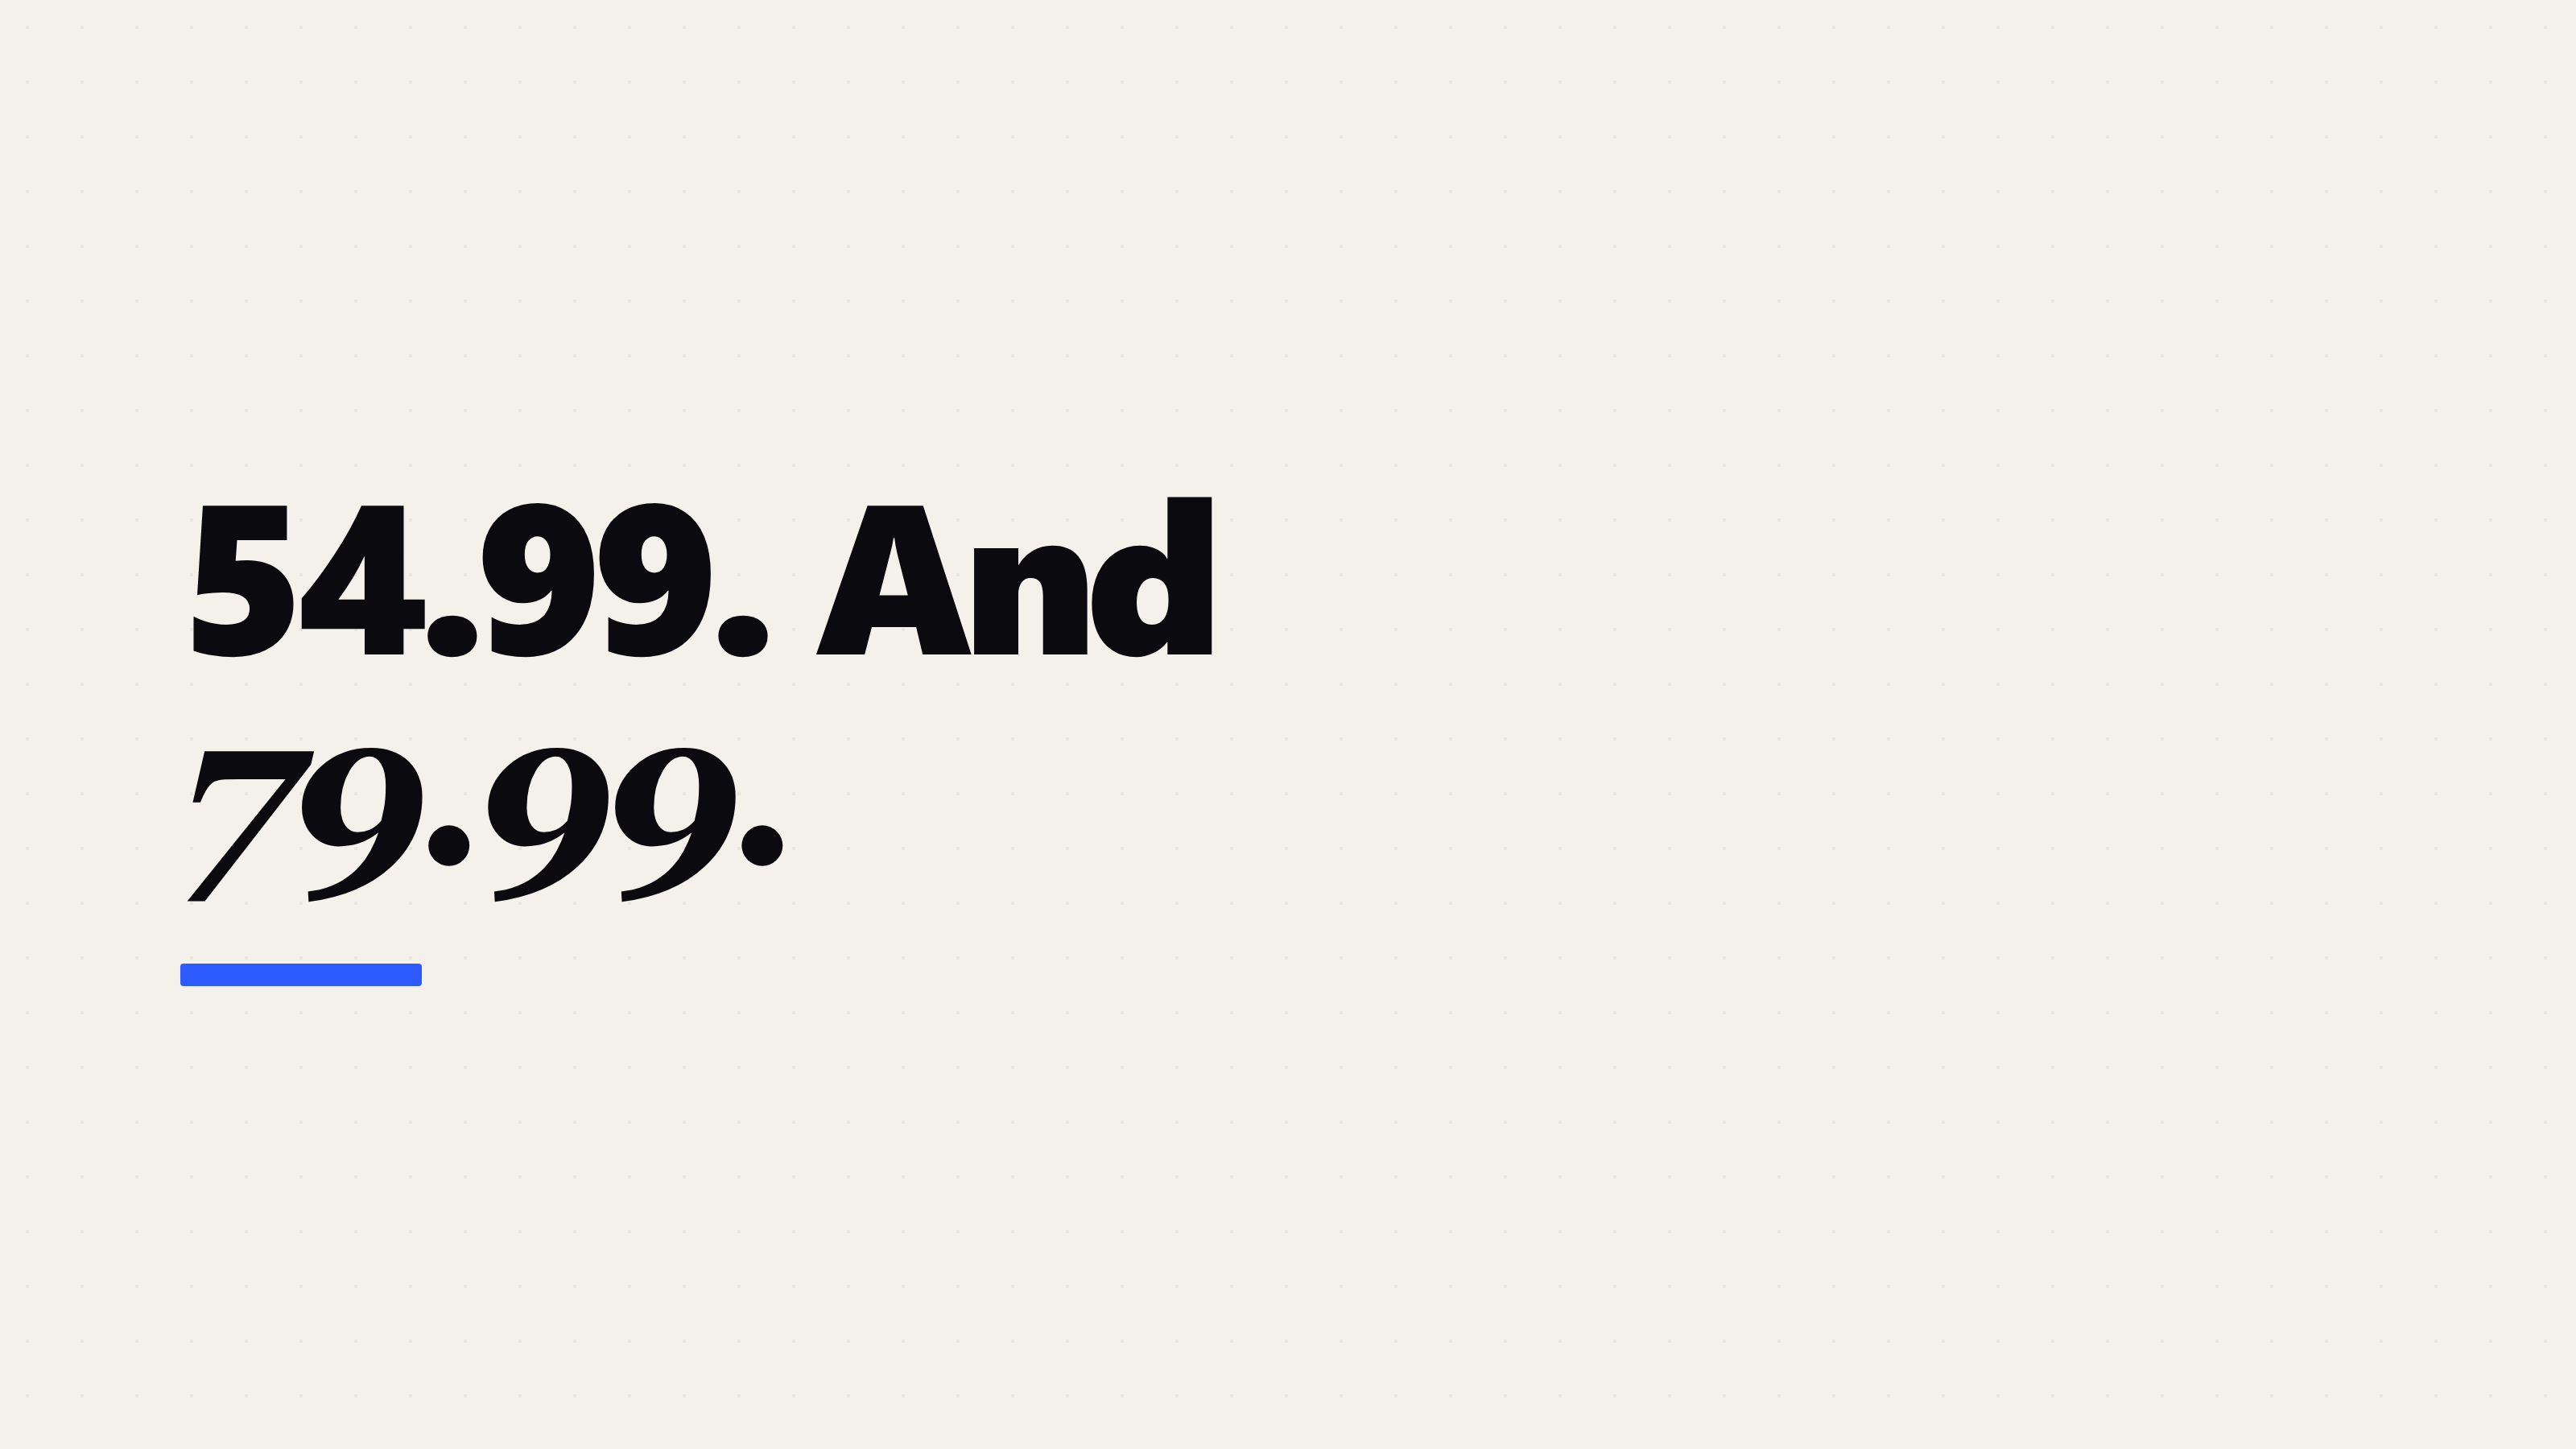
How to Monitor Competitor Prices Automatically
Two sources agreed the price was 54.99. One also said the list price was 79.99. Store only the first and you cannot tell a price cut from a discount.
Kalshi API and Polymarket: Matching Prediction Markets by the Call
Two Kalshi routes returned 15 and 25 fields for one venue, with no tickers in common. The cross-venue match endpoint returned 20 pairs at 100 percent.
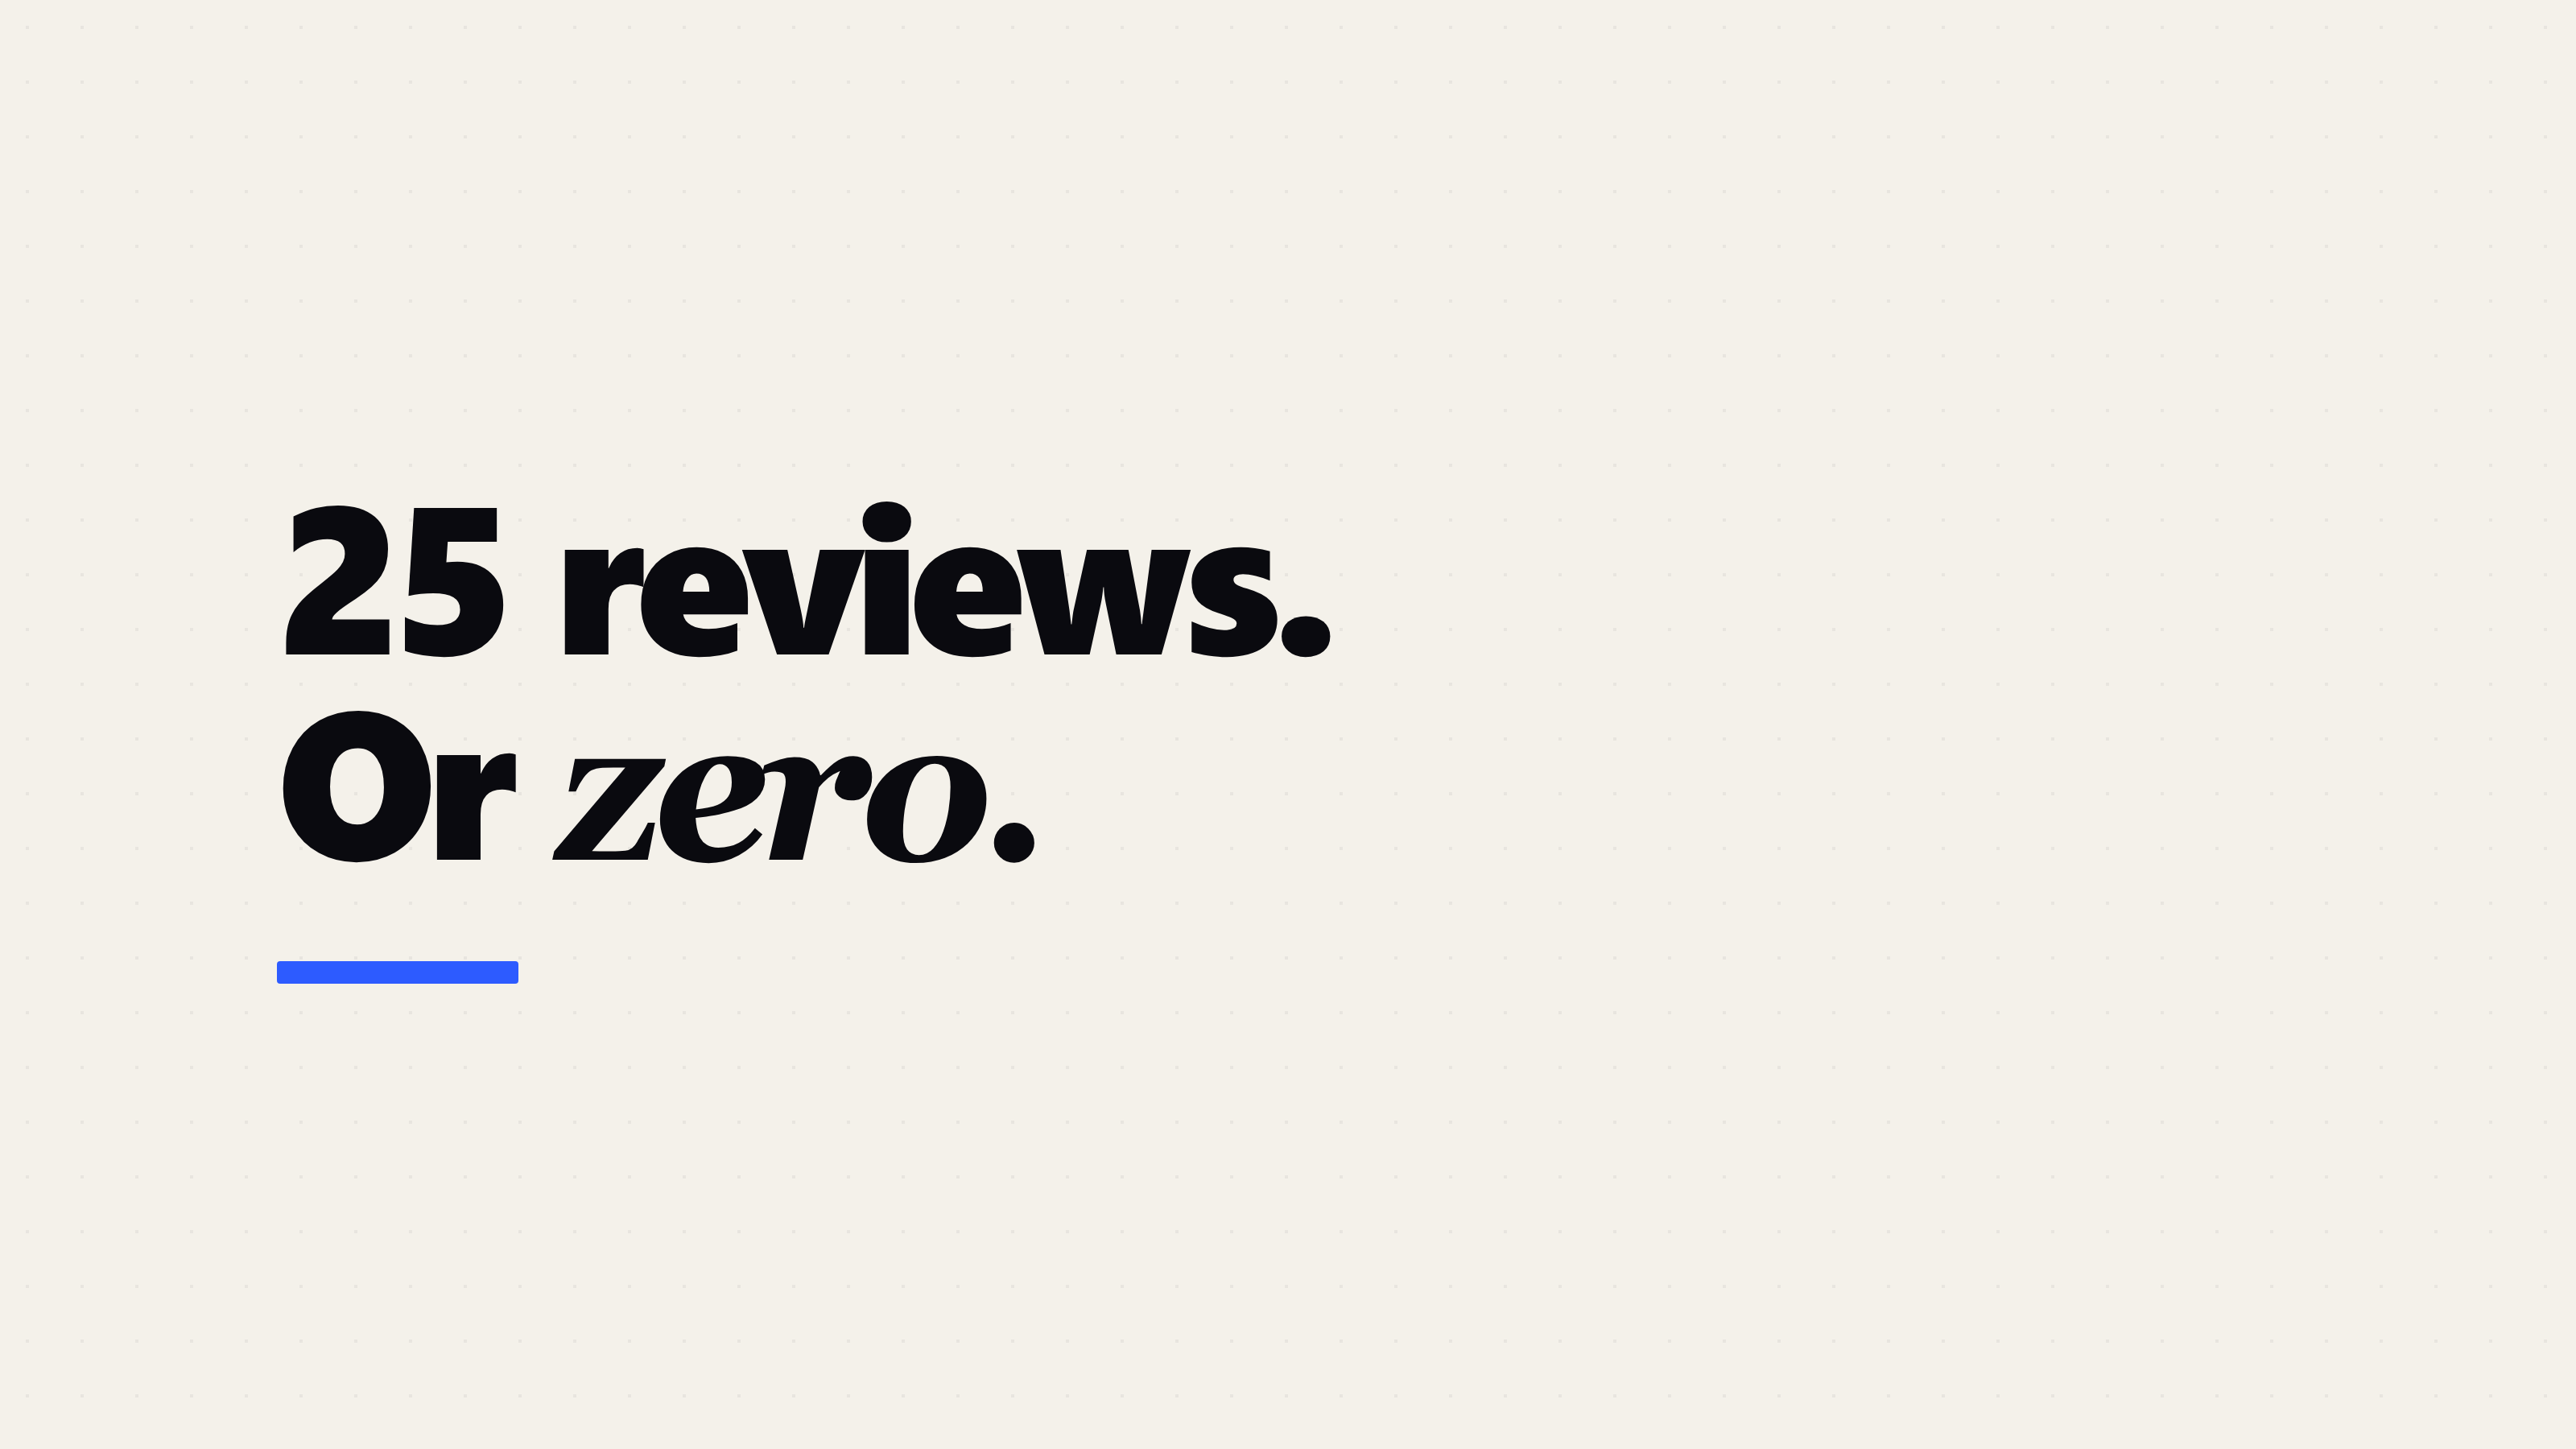
Software Review Data: What a G2 or Capterra API Returns
Capterra returned 25 reviews split into pros and cons. A niche product returned zero. G2 was blocked on both days we tried, five days apart.
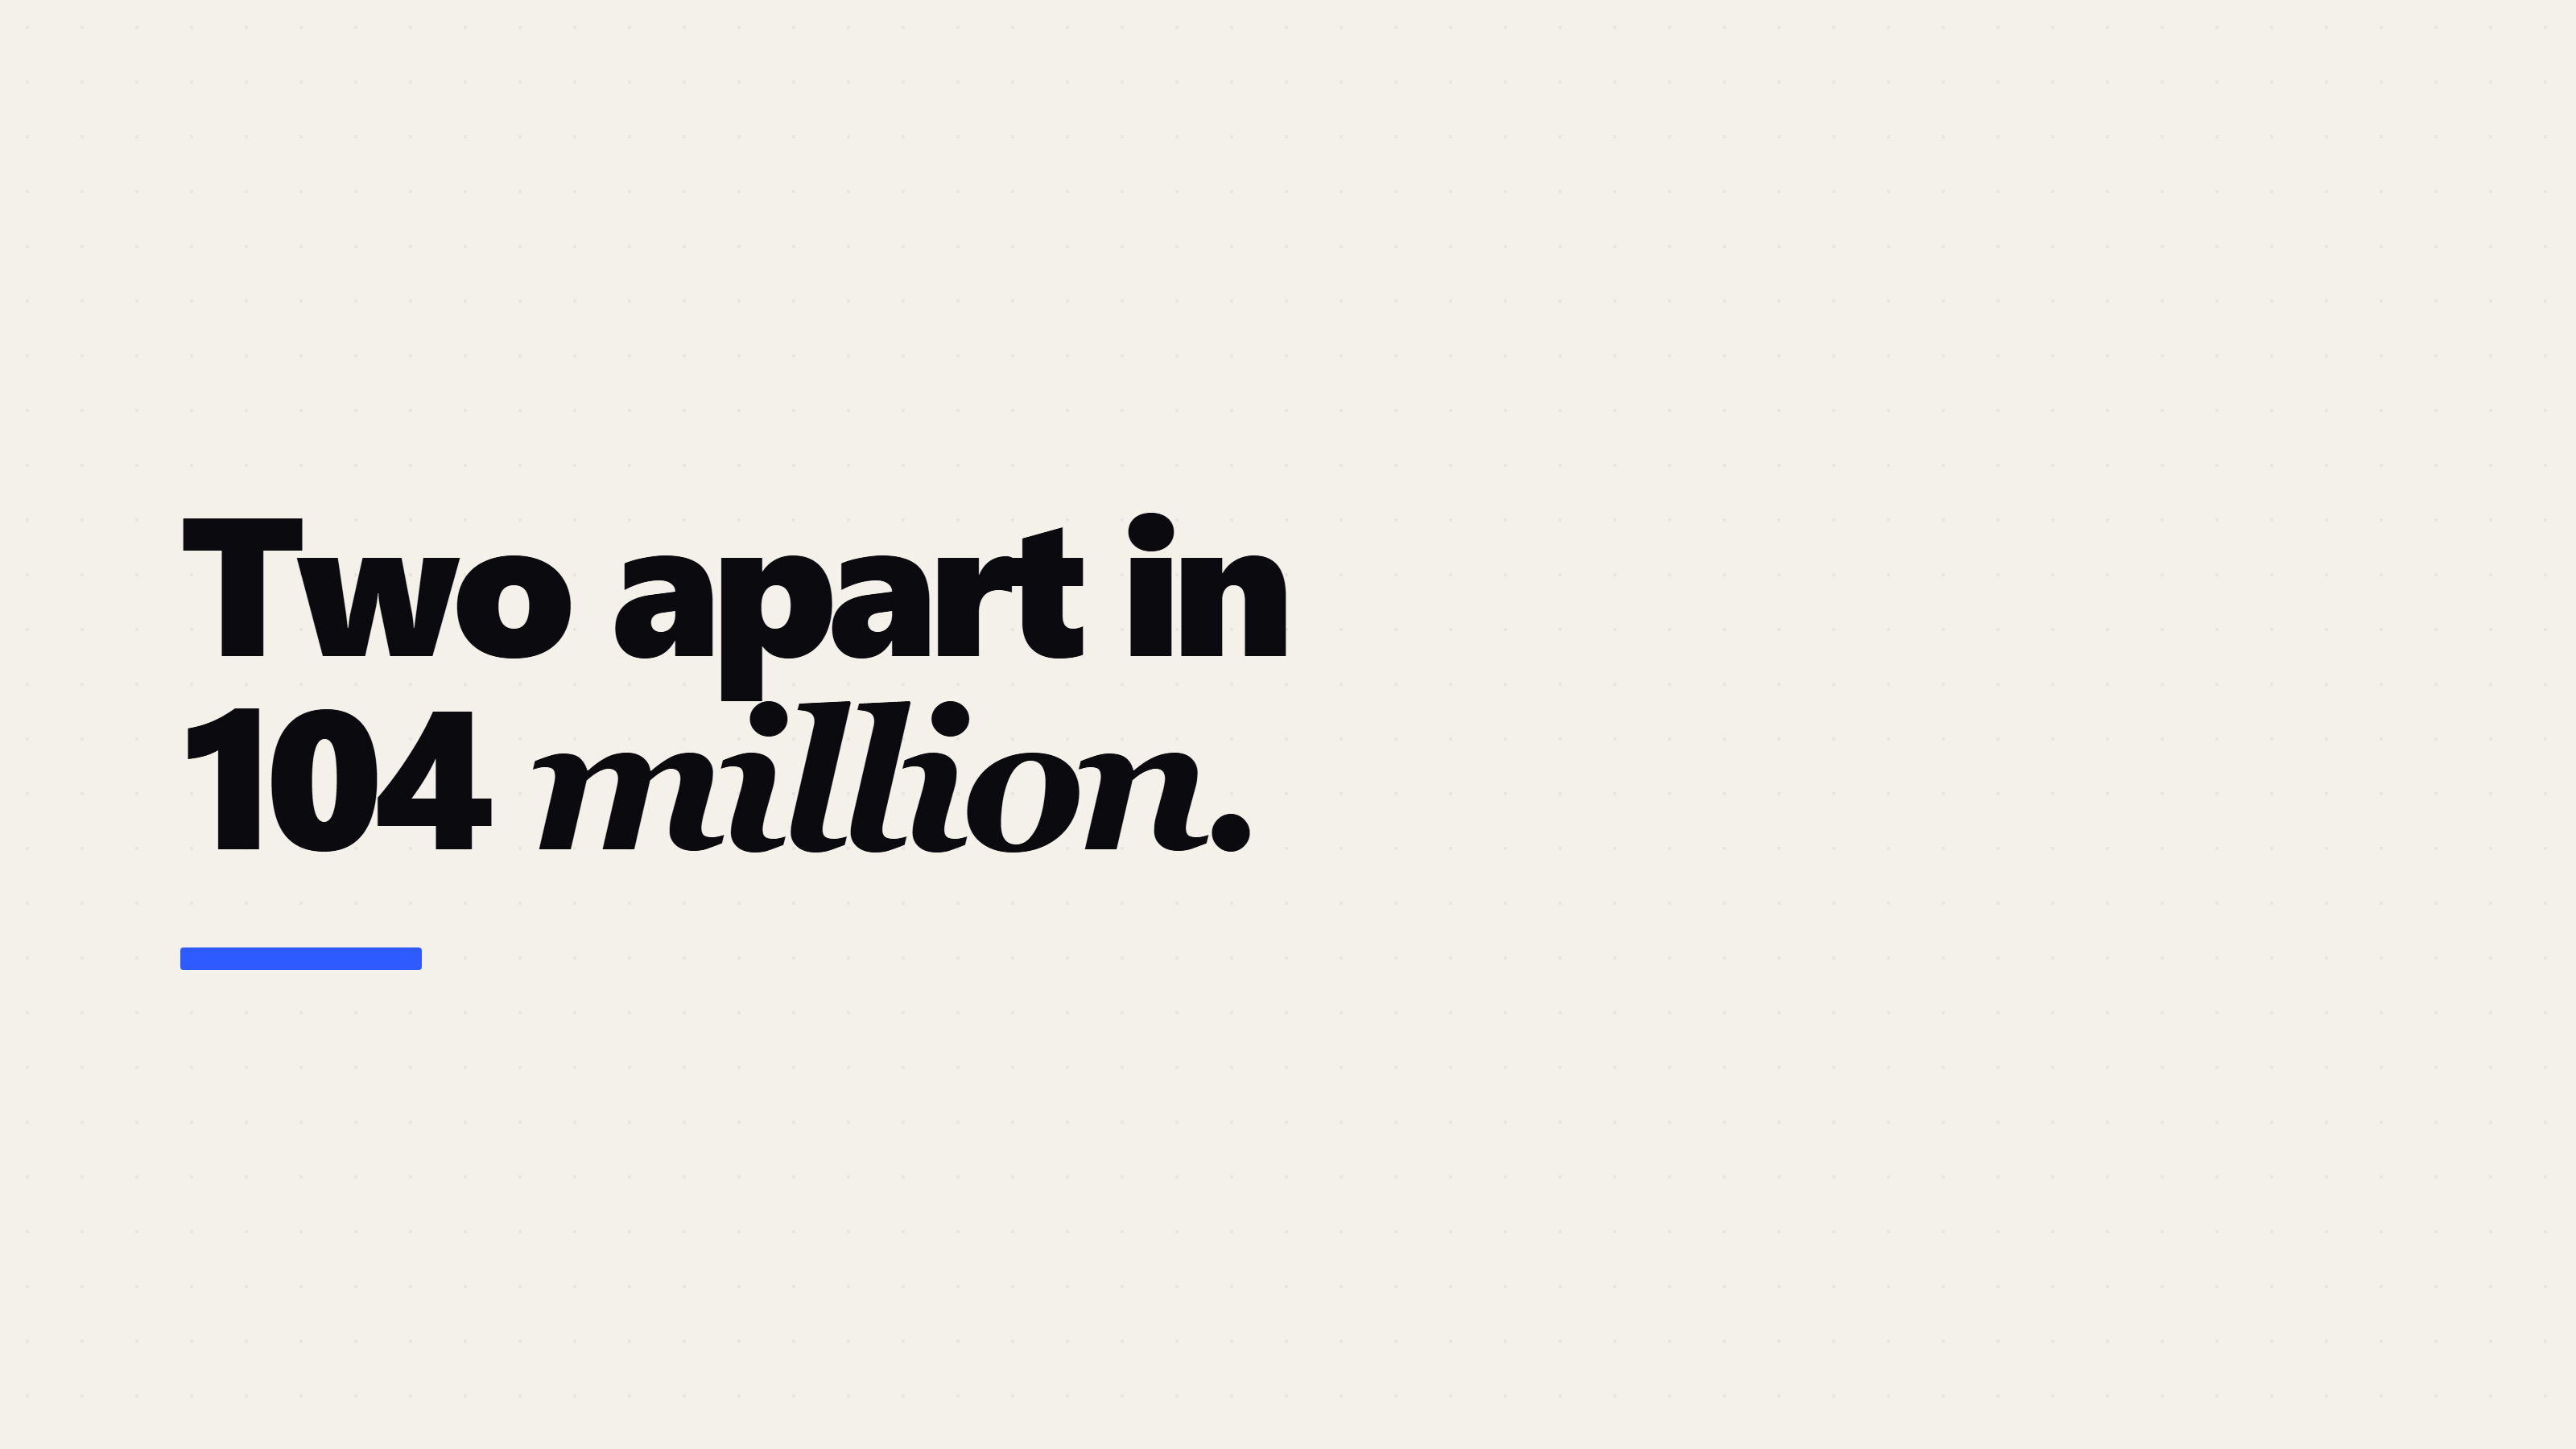
Are Instagram Follower and Engagement Trackers Accurate?
Two providers disagreed by 2 followers out of 104 million. The same 12 posts gave 0.096% or 0.334% engagement depending on one undocumented choice.
Bounce Rates and Spam Traps When Validating an Email List
A verifier returned twelve fields for three addresses. None of them was spam_trap, and none could be. Here is what verification fixes and what it cannot.
How to Rate Limit Calls to a Third Party API
Six real failure responses collected over three days. Only one of them meant slow down, and telling them apart matters more than any backoff algorithm.
How to Scrape LinkedIn Without Getting Your Account Banned
The ban risk comes from tools that drive your logged-in session. Three endpoints returned profile data from a URL alone, with no cookie involved.
How to Stop Depending on One Scraping Vendor
Ten provider failures in three days, all while doing other work. None was a bad vendor. The defence is a second route you can reach without a rewrite.
Extract Pricing and Free Trial Information From Websites
One endpoint returned four plans, numeric amounts and a free_trial_available flag. It also disclosed that a model read the page, which changes everything.
Find All Pages on a Domain: Sitemap, Map or Crawl
One map call returned 1,139 pages for a site whose sitemap declared 1,113. Three of four sitemaps returned an index and no count at all.
MLS Real Estate API: What You Get When You Cannot Get MLS
MLS access needs a licence and a broker. Two public sources returned 40 listings and 48 agents with phones. What they carry, and what they do not.
Simply Wall St GraphQL API: What Returns Fundamentals Instead
There is no public Simply Wall St GraphQL API. An endpoint that does return fundamentals gave 26 line items across six periods, and named its own source.
Amazon ASIN Scraper: What to Do When It Returns Nothing
A purpose-built ASIN endpoint returned 26 fields and zero values for two valid ASINs. A generic extractor read the same page fine. Assert on values.
Datacenter Proxies vs Residential: What Each One Actually Fixes
A real residential IP with a real Chrome user agent still got 403 from two sites. The IP type was not the constraint. What each type does fix.
Extracting Leadership Contact Information Without Paying to Look
Hunter's multi-domain search returned 404,695 matching executives for free, names masked and titles visible. You pay only for the addresses you choose.
Puppeteer Extra Plugin Stealth: Check the Release Date First
The stealth plugin last shipped in March 2023. Puppeteer shipped last week. What that gap means, and what scrapy-playwright does differently.
C# Web Scraping: Keep HtmlAgilityPack, Drop the Fetch
The .NET parsing stack was never the problem. What breaks a C# scraper is the request leaving your server, and that half is not a language question.
LinkedIn Post Scraper: What Actually Comes Back
Posts, reactions and comments are three billing decisions in one call. A live run shows the fields, and the two flags that quietly multiply the bill.
Web Scraping vs API: You Are Choosing a Maintainer
Both end in an HTTP request returning the same facts. What differs is who owns the parser when the page changes, and whether anyone promised you anything.
XPath Cheat Sheet: The Dozen Expressions That Survive
Most XPath references list what the spec allows. This lists what still matches after a redesign, ranked by how long each anchor survives.